Scaling Beyond a Billion Transactions Per Day with Sub-second Responses

Scaling Beyond a Billion Transactions Per Day with Sub-second Responses

  • January 23, 2020
Table of Contents

Scaling Beyond a Billion Transactions Per Day with Sub-second Responses

Andrey Zolotov, Gideon Low present their journey of transition to distributed data processing using GemFire and the challenges faced along the way.

Source: infoq.com

Share :
comments powered by Disqus

Related Posts

The Biggest IT Failures of 2018

The Biggest IT Failures of 2018

This year provedonce againthat IT-related failures “are universally unprejudiced: they happen in every country; to large companies and small; in commercial, nonprofit, and governmental organizations; and without regard to status or reputation.” Below is a review that just scratches the surface of the sundry failures, glitches, and other IT hiccups that made the news in 2018. This year saw a slight reduction in the number of flight cancellations and delays due to computer-related problems as compared with the past three years, especially in the United States.

Read More
Database Migration To Amazon Aurora

Database Migration To Amazon Aurora

In this blog post we’ll show you how we migrated a critical Postgres database with 18Tb of data from Amazon RDS (Relational Database Service) to Amazon Aurora, with minimal downtime. To do so, we’ll discuss our experience at Codacy.

Read More
Observability at Scale: Building Uber’s Alerting Ecosystem

Observability at Scale: Building Uber’s Alerting Ecosystem

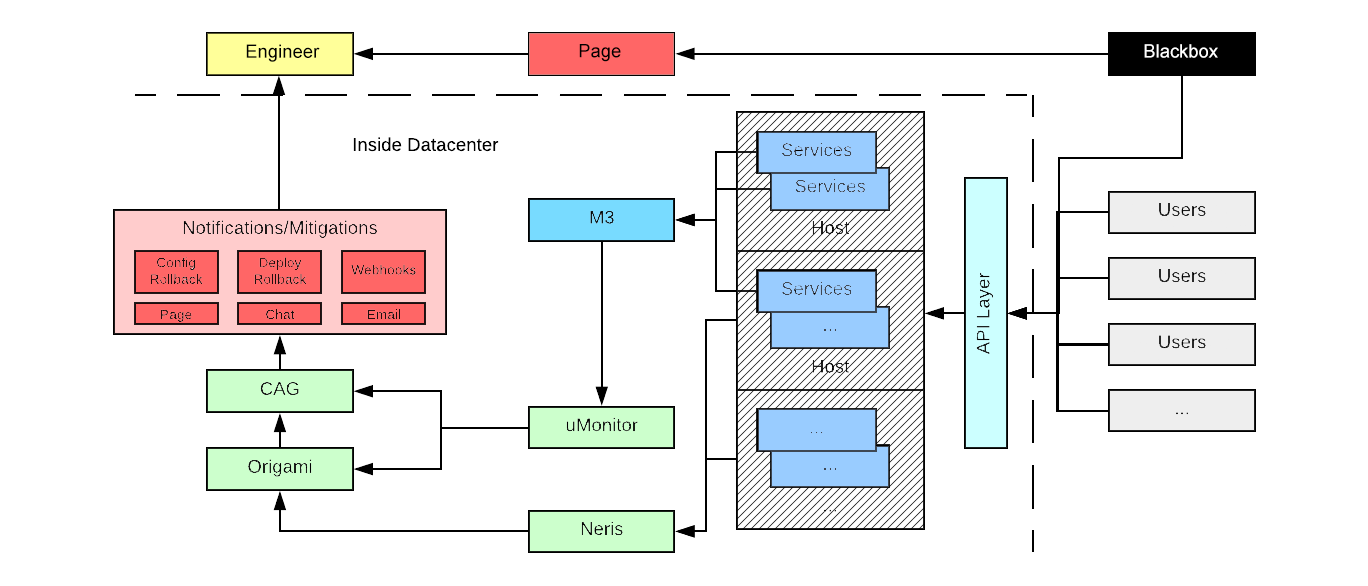
Uber’s software architectures consists of thousands of microservices that empower teams to iterate quickly and support our company’s global growth. These microservices support a variety of solutions, such as mobile applications, internal and infrastructure services, and products along with complex configurations that affect these products at city and sub-city levels. To maintain our growth and architecture, Uber’s Observability team built a robust, scalable metrics and alerting pipeline responsible for detecting, mitigating, and notifying engineers of issues with their services as soon as they occur.

Read More