Telltale: Netflix Application Monitoring Simplified

Telltale: Netflix Application Monitoring Simplified

  • October 15, 2020
Table of Contents

Telltale: Netflix Application Monitoring Simplified

Our Netflix teams need to quickly detect, diagnose, and remediate problems. Telltale is intelligent monitoring and intelligent alerting. The Telltale application health model yields intelligent monitoring and intelligent alerting.

Netflix service owners get alerts they can trust with little configuration and no need for constant tuning. When health problems strike, Telltale presents only the most relevant context and suggests possible causes. An alert fires and you get paged in the middle of the night.

A metric crossed a threshold. You’re half awake and wondering, “Is there really a problem or is this just an alert that needs tuning? When was the last time somebody adjusted our alert thresholds?

Maybe it’s due to an upstream or downstream service?” This is a critical application so you drag yourself out of bed, open your laptop, and start poring through dashboards for more info. You’re not yet convinced there’s a real problem but you’re also aware that the clock is ticking as you dig through a mountain of data looking for clues.

Source: netflixtechblog.com
Share :
comments powered by Disqus

Related Posts

Infrastructure monitoring: Defense against surprise downtime

Infrastructure monitoring: Defense against surprise downtime

Infrastructure monitoring is an integral part of infrastructure management. It is an IT manager’s first line of defense against surprise downtime. Severe issues can inject considerable downtime to live infrastructure, sometimes causing heavy loss of money and material.

Read More
MTTR is dead, long live CIRT

MTTR is dead, long live CIRT

The game is changing for the IT ops community, which means the rules of the past make less and less sense. Organizations need accurate, understandable, and actionable metrics in the right context to measure operations performance and drive critical business transformation. The more customers use modern tools and the more variation in the types of incidents they manage, the less sense it makes to smash all those different incidents into one bucket to compute an average resolution time that will represent ops performance, which is what IT has been doing for a long time.

Read More
Kubernetes Metrics and Monitoring

Kubernetes Metrics and Monitoring

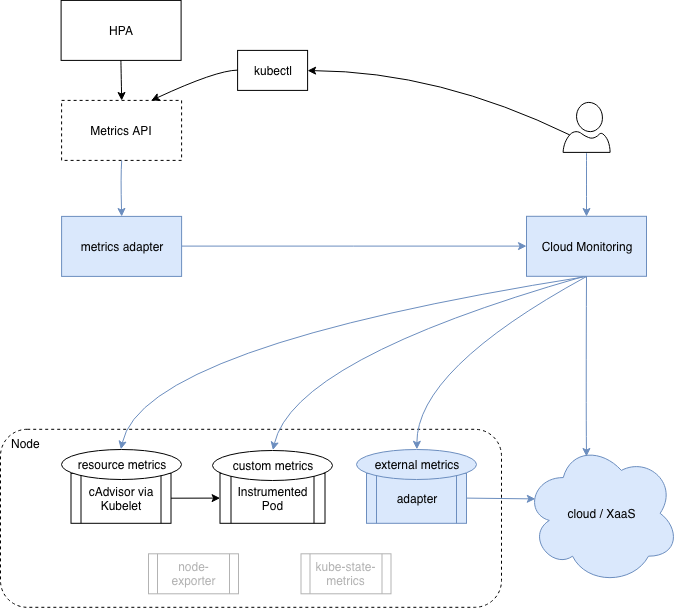
This post explores the current state of metrics and monitoring in Kubernetes by walking through the gradual thought process that I experienced when learning this topic. Kubernetes needs some metrics for it’s basic out-of-the-box functionality, like autoscaling and scheduling. This is regardless of any monitoring solution you may want for the purpose of troubleshooting and alerting.

Read More